Domino/Notes Version: 14.5.1 FP1 Add-on Product (if appropriate, e.g. Verse / Traveler / Nomad / Domino REST API):Llama Server for Domino IQ Its Version:14.5.1 Operating System: Windows Server 2025 Client (Notes, Nomad Web, Nomad Mobile, Android/iOS, browser version):
Hi all,
I’m trying to install DominoIQ on a brand new lab server.
NVIDIA A10 GPU with 8 GB of dedicated RAM, driver NVidia 581.42. All seems to be ok with hardware.
On loading, Domino console displays “DominoIQTask : le moteur IA domino IQ s’est arrêté demanière imprévue”, that we can translate into “Domino IQ engine stopped unexpectedly”.
In the dominoiq_server_log file, we found this:
**********
main: loading model
srv load_model: loading model ‘E:\Data\llm_models\Llama-3.2-3B-Instruct-Q4_K_M.gguf’
common_init_result: fitting params to device memory, for bugs during this step try to reproduce them with -fit off, or provide --verbose logs if the bug only occurs with -fit on
llama_params_fit_impl: getting device memory data for initial parameters:
CUDA error: operation not supported
current device: 0, in function ggml_backend_cuda_device_get_memory at V:\llama.cpp\ggml\src\ggml-cuda\ggml-cuda.cu:4610
cudaMemGetInfo(free, total)
V:\llama.cpp\ggml\src\ggml-cuda\ggml-cuda.cu:98: CUDA error
**********
HCL support tells me that it’s not in the Domino perimeter… so I need help to get my DominoIQ just starting !
Good Day, just a quick question about the setup that you have:
Is this Domino Lab Server running on a bare-metal machines or inside a virtual machines?
If it is a VM: Which hypervisor are you using?
How is the nvidia a10 assigned to the VM? Is it via Direct PCIe Passtrough or an NVIDIA vGPU profile slice?
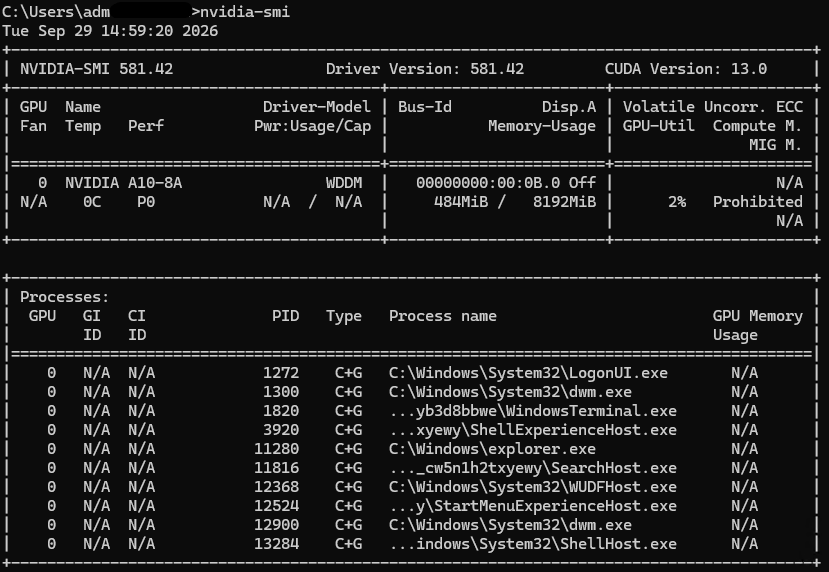
Could you run the following commands in an elevated Command Prompt/Terminal on the guest OS and share the output?
nvidia-smi
nvidia-smi --query-gpu=memory.total,memory.free,memory.used,compute_mode --format=csv
now, my question is Does nvidia-smi throw any error, or does it display the memory stats cleanly?
In your dominoiq.nsf database, Is GPU Offloading set to Automatic or Enabled?
What happens if you temporarily set GUP Offloading to Disabled? Does dominoiq.nsf load the llama model successfully on the CPU?
The issue you are encountering “CUDA error: operation not supported at cudaMemGetInfo” is caused by a structural limitation of the A10-8A profile.
When you run an A series (Virtual Applications) profile on a Windows guest, the NVIDIA GRID driver restricts certain CUDA API operations. Specifically, calls like cudaMemGetInfo which llama.cpp uses to safely scan and fit parameters to the GPU’s available memory are actively blocked or unsupported on A profiles.
What I can recommend is to change the GPU profile that you have from A10-8A to A10-8C or A10-8Q.
Use A10-8C if this Windows VM is a Headless/Backend Worker or use A10-8Q if this Windows VM is an Interactive User Desktop. Both this profile will expose some CUDA APIs that you need.